Square
Following
Hot
News
Profile

Stephan_

vip
Active for: 3.6y
Peak Tier 0
No content yet
0
Following
2
Followers
24
Liked
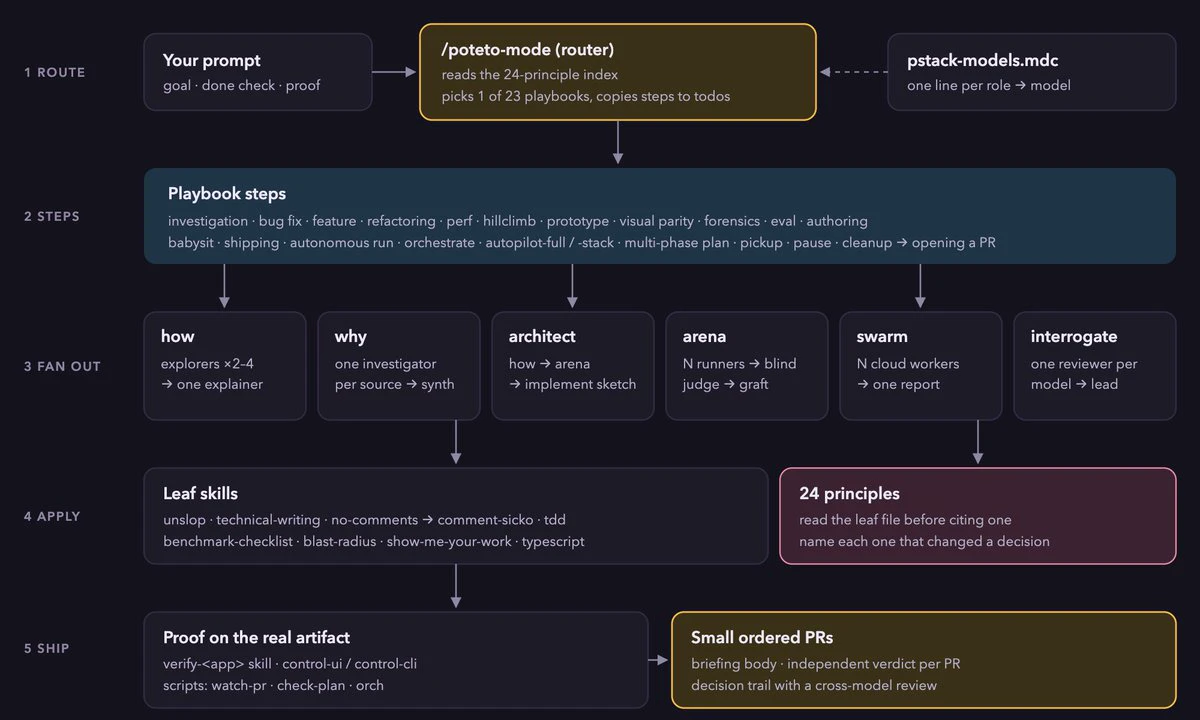
I’ve recently been systematically studying @poteto’s pstack—truly amazing! It feels like a whole new world has opened up!
I’ll share what I learn along the way:
post-image
The best-value subscription right now isn't opencode-go
Nor is it commandcode-goat
It's ChatGPT-plus 😂
Recently, I’ve been thinking about a question: when writing skills for frontier models, how should we strike a balance between determinism and flexibility?
By determinism, I mean writing skills with more hard constraints or code.
By flexibility, I mean using fewer details and constraints, and writing skills from a high-level, prompt-driven perspective.
There needs to be a dynamic balance between the two; there is no single right answer.
This came up while comparing matt’s /spec-implement with my /pi-matt-implement-flow.
My process and framework impose many constraints. The benefit is greater d
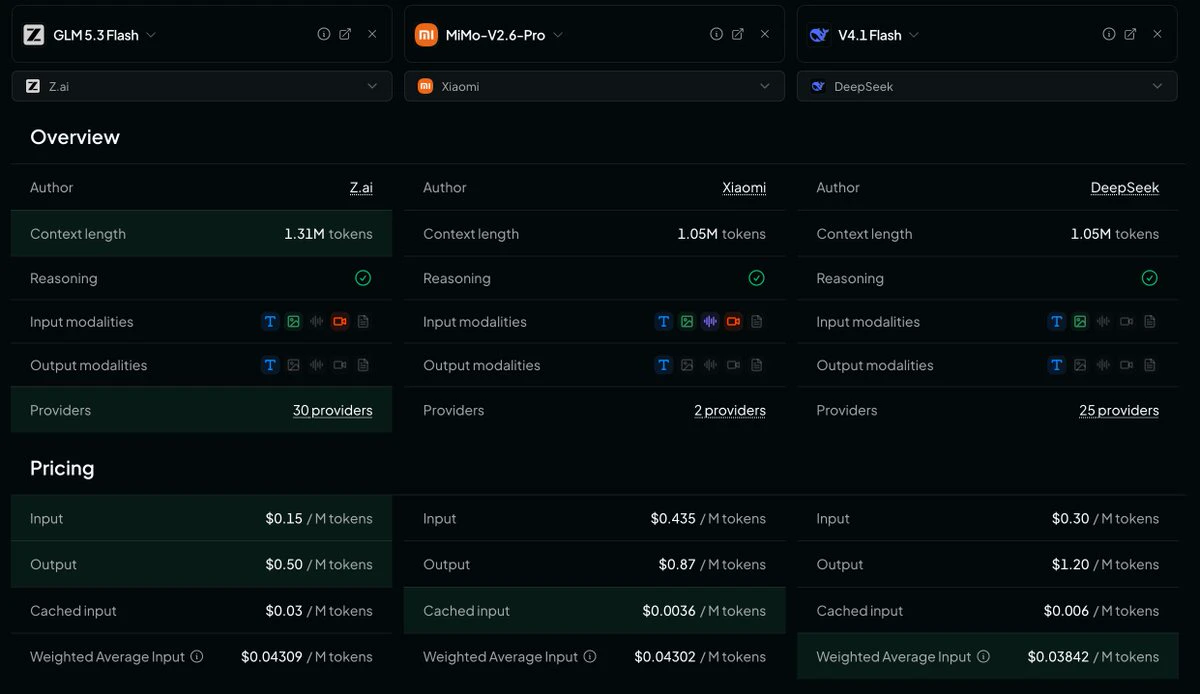
Based on OpenRouter's actual Weighted Average Input, the costs of these three models are very close. So if you had to choose one of the three as your primary model, which would you choose?
post-image
The official npm registry is down just as I was preparing to register with the official npm registry and publish a package 😤
Recent thoughts🤔:
More R&D time should be spent developing eval datasets and evaluating their accuracy and comprehensiveness, then using an eval loop to drive business iteration
rather than directly vibe coding business code
Ideally, with a reasonable goal + eval loop, the business code should be able to iterate on its own
I’m trying to make this transition and welcome discussion.
Why do the scores from many AI benchmarks not quite match our own experience?
I think the key is that most benchmarks are like firing the starting gun and seeing who can run the farthest.
They do not care where the models run—even running into the sky is fine. The entire evaluation process does not need to converge.
In real-world scenarios, the most challenging part is the process of convergence and alignment. Running far does not necessarily mean being good; the best models are those that can keep running within the track.
I used grok to create an automated task that tracks the quotas and estimated monthly call counts of the mainstream models in commandcode GOAT, sorted by call count. Sharing it here:
post-image
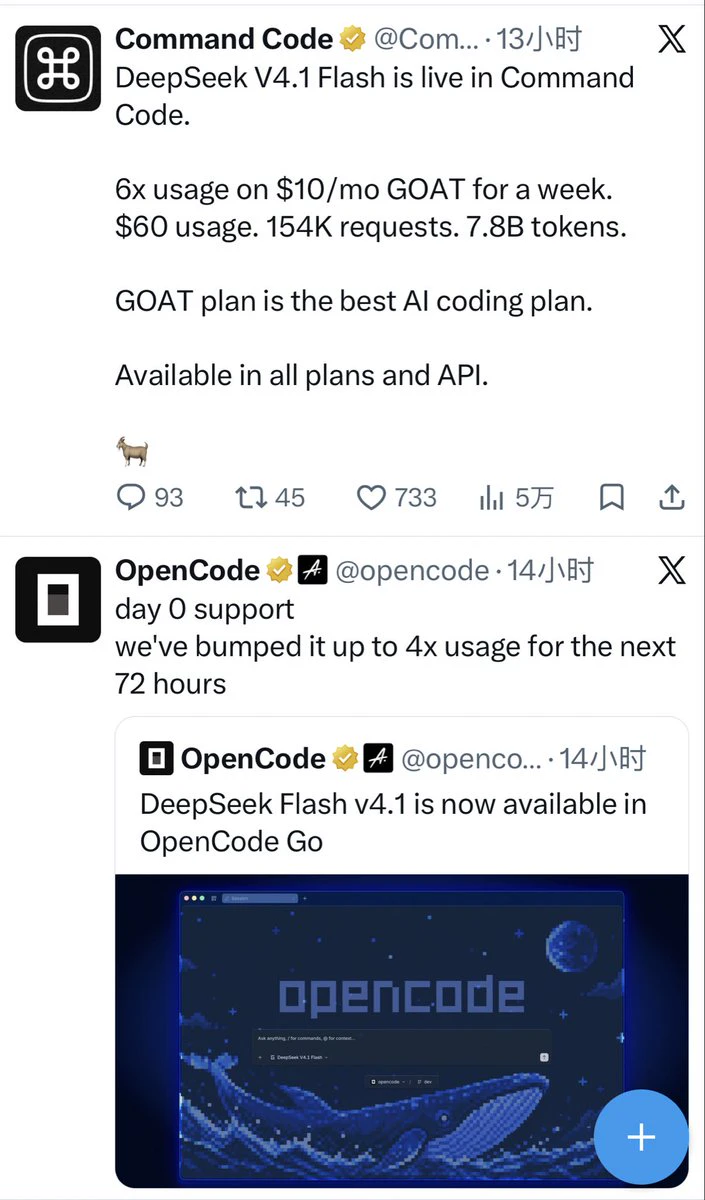
OpenCode-Go: For the next three days, we will give everyone 4x ds-4.1 quota😆
CommandCode-GOAT: For the next seven days, we will give 6x quota🥹
post-image
4+2.09%
GOAT-0.43%
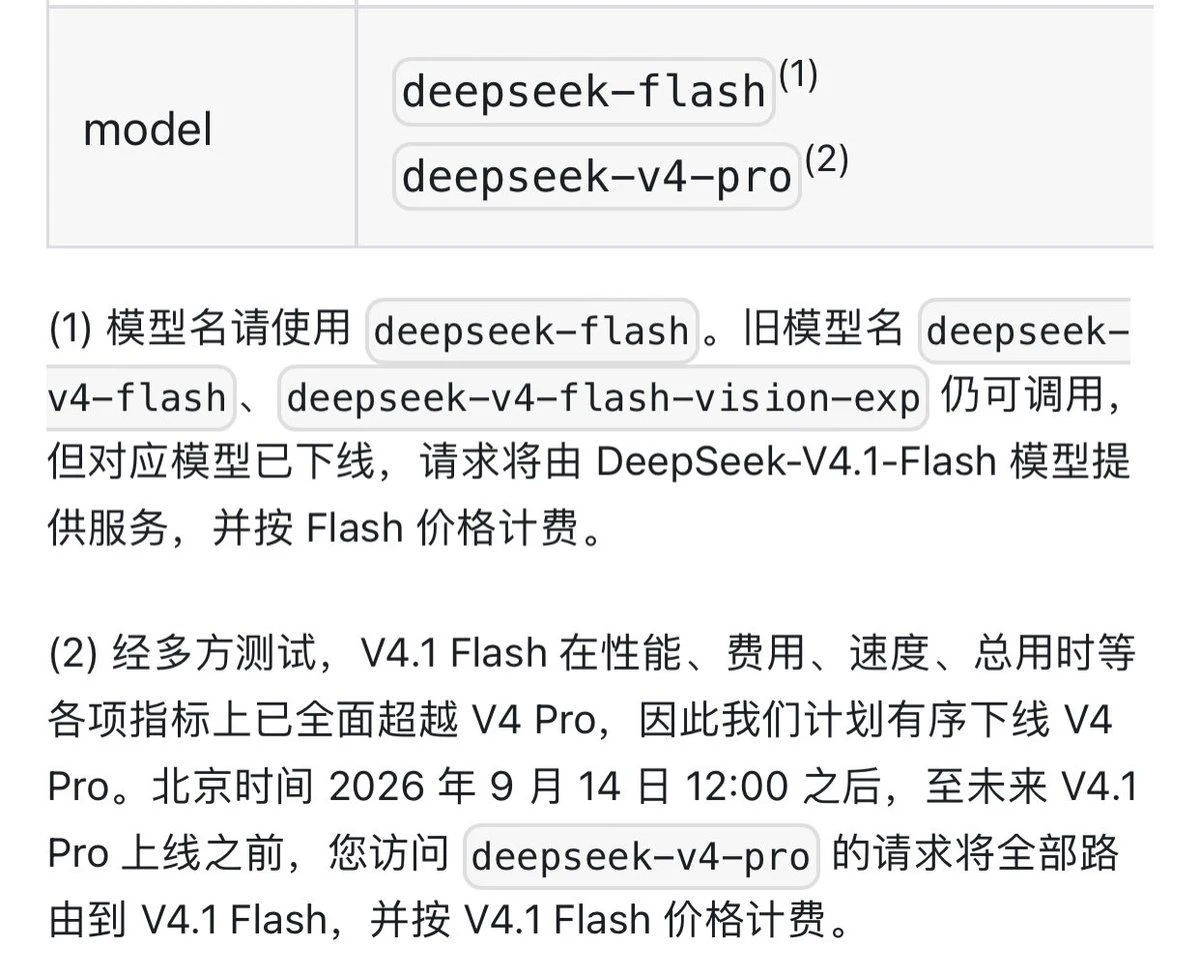
DS, this is total unification—the entire site has only one model 😂.
post-image
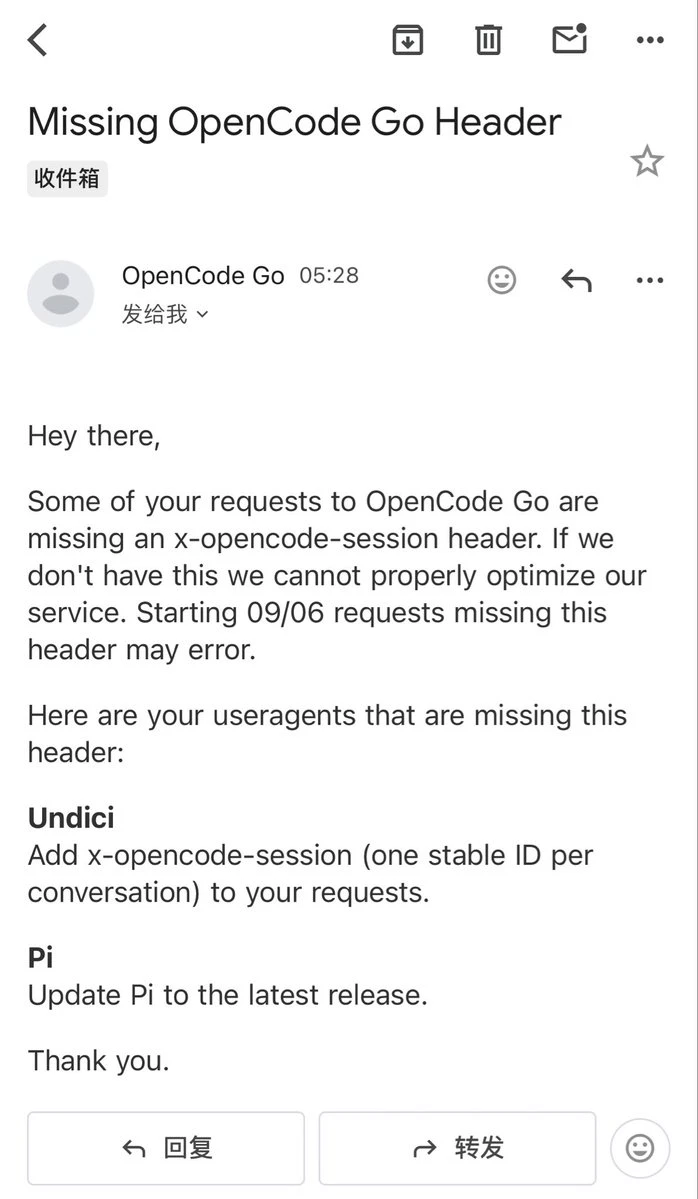
I've been subscribing to pi + opencode-go for some time, and I just received the following email.
This whole thing feels a bit strange. A provider is emailing a harness's customer, telling them to upgrade as soon as possible, otherwise they won't be able to use us anymore.😂
Also, why isn't this UA pi-agent? Is Undici the SDK used for pi's underlying communications?
post-image
After getting used to Deepseek-v4-flash, I really can't stand GLM-5.3-flash anymore 😂
The key issue is that GLM is slow, which would be fine, but it also throws errors all the time, so its stability isn't great
In that case, you can completely use a stronger model for planning and deepseek-v4-flash for execution instead.
DEEPSEEK+7.30%
GLM-2.12%
Think about a question: Is there a framework that can turn a complete SaaS service template + AI harness + custom skills into a pluggable framework?
Could DeepSeek Harness become such an infrastructure? Are there any other mature projects?
DEEPSEEK+7.30%
The smart zone mentioned by Matt Pocock is a context length of around 120K. My experience with grok-4.6 is pretty similar—once it gets close to 200K, it noticeably becomes less intelligent. What has everyone else’s experience been? Do other models also have a clear smart zone?
grok build is the best TUI I’ve ever used. Now paired with grok-4.6, it’s arguably the king of value for money. Most importantly, grok is faster than many top-tier models, and if its quality can reach the first tier, its competitiveness will be incredibly strong (and you can top up freely without getting your account banned)!
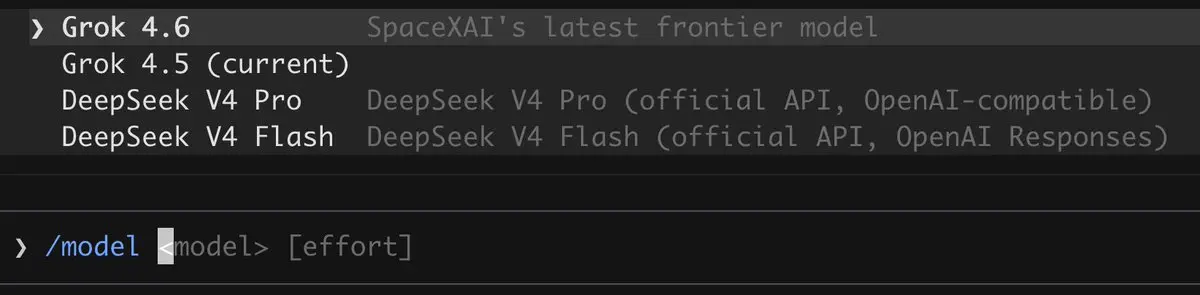
grok-4.6 & deepseek-v4-pro have been released simultaneously!
post-image
After watching the three and a half hour podcast of Lao Luo interviewing Zhou Hongyi, it is evident that Lao Zhou has a lot of practical industry experience. Unfortunately, Lao Luo's questions are not deep or professional enough, which is a bit regrettable.
For example, when Lao Luo mentioned that the top overseas models are this viewpoint, I think it is somewhat biased. Because different fields have different best models, for instance, in the programming field, both Claude-4 and GPT-5-Codex may currently be superior; and also, regarding the LLM hallucination problem that Lao Zhou has ment
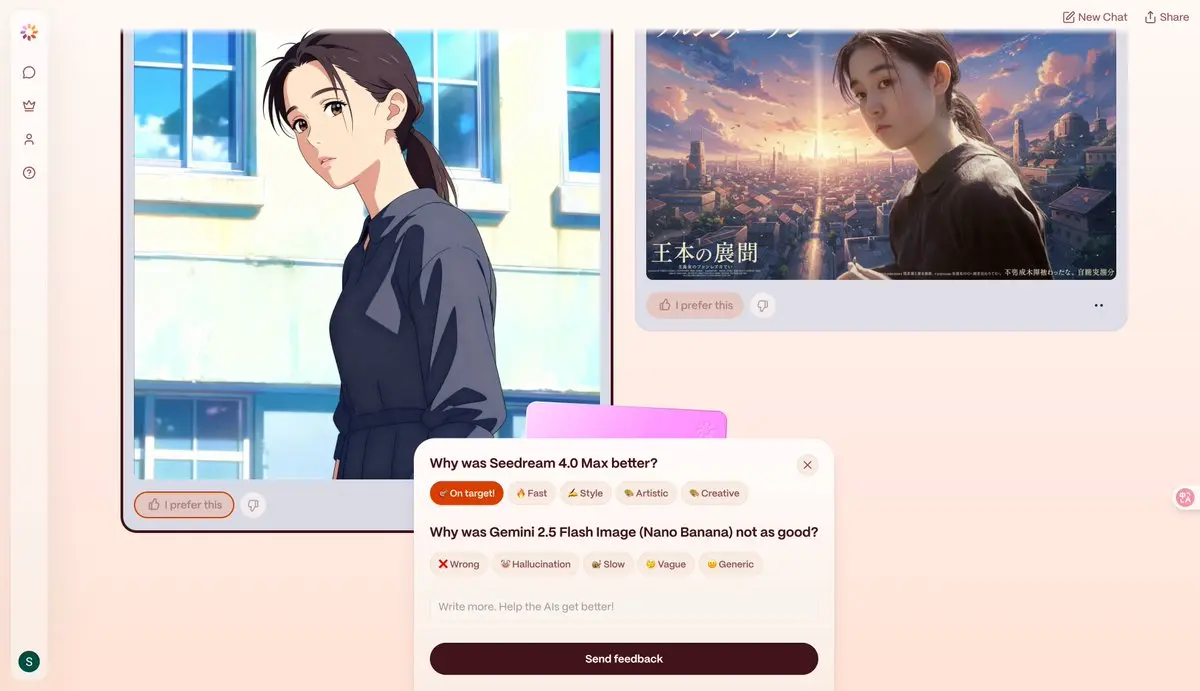
yupp this website is interesting, it allows free use and comparison of the most advanced AI models
Every conversation on yupp has at least two AI large models responding to you at the same time, and you can choose the answer you think is better and share your usage feedback with yupp.
User feedback can earn points, and higher quality feedback can earn more points. More points mean you can use more advanced models and even withdraw points.
The reason this website can offer free access to large models is directly related to the user feedback mechanism it has established. This feedback data will
post-image
OpenAI has released a "GPT-5 Coding Guide", which provides 6 best practices for using GPT-5 for AI programming:
# 1. Instructions should be precise to avoid information conflicts
The new GPT-5 model has significantly improved its ability to follow instructions, but this also brings a side effect: it may struggle when faced with vague or conflicting instructions. This situation particularly requires attention in your .cursor/rules or configuration file.
# 2. Set the appropriate reasoning level
GPT-5 always engages in a certain level of reasoning when solving problems. To achieve the best result
XPRT+12.08%