Square
Following
Hot
News
Profile

GateUser-ebc4af76

vip
Active for: 12.8y
Peak Tier 6
No content yet
0
Following
9
Followers
20
Liked
I tested GPT-6 Sol for two days, and I have one piece of advice for everyone!
Its capabilities are far inferior to GPT-5.6 Sol; it is merely an upgraded version of GPT-5.6 Terra. It can basically be confirmed that it is a small-parameter model, so no wonder its price is also about the same as the original GPT-5.6 Terra.
I speculate that running GPT-5.6 Sol requires a lot of computing power, making it far less worthwhile than reallocating that computing power to GPT-6 Astra. That is why they are rushing to take the original GPT-5.6 Sol offline.
[New] DeepSeek full-power models now online, all at 50% off!
DeepSeek full-power models directly supplied by major domestic providers are now online. This launch includes:
DeepSeek-V4-1-Flash-0910
DeepSeek-V4-Pro-0813
DeepSeek-V4-Flash-0731
All the above models are available at 50% off, with quality comparable to the official versions and stable service, making them suitable for production environments!
👉 Detailed model IDs and pricing:
OpenAI has upgraded its risk controls, and it is no longer even pretending not to dumb things down!
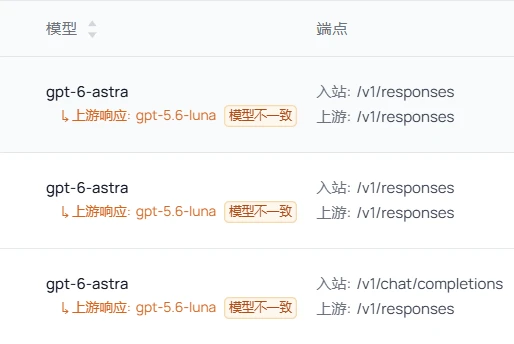
Today, I suddenly discovered that some accounts were receiving abnormal model responses. Although they were clearly accessing GPT-6 Astra, the upstream OpenAI model actually responding was GPT-5.6-luna.
I conducted a careful investigation. Although only a few accounts have encountered this issue, this sign indicates that OpenAI may have begun gray testing of this new way of dumbing down models.
Users accessing the service through my relay station who encounter the above situation will automatica
post-image
  • 2
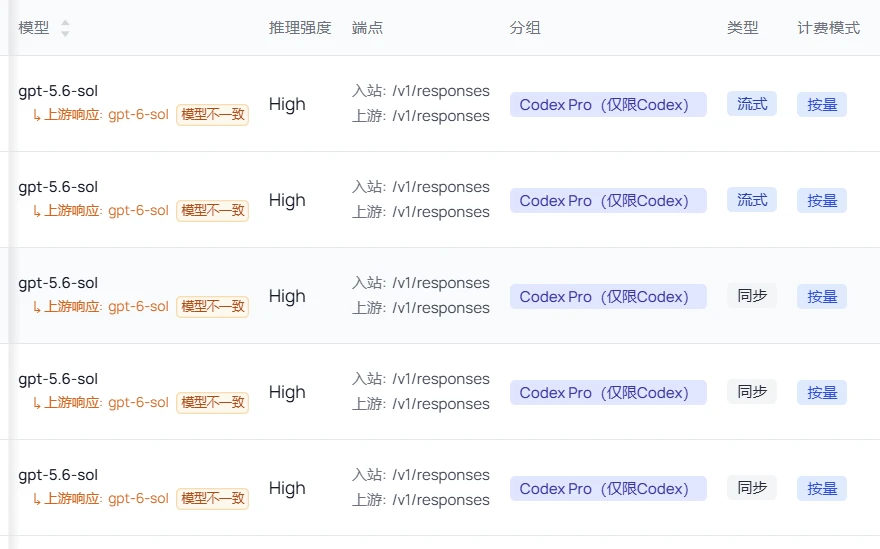
OpenAI has already quietly begun a gradual rollout of GPT-6 Sol; many of our requests to 5.6-sol are actually calling GPT-6 Sol.
It looks like the company will release this new model soon, and I estimate its intelligence will be second only to GPT-6 Astra, while its price will remain the same as GPT-5.6 Sol’s, which is still quite appealing.
post-image
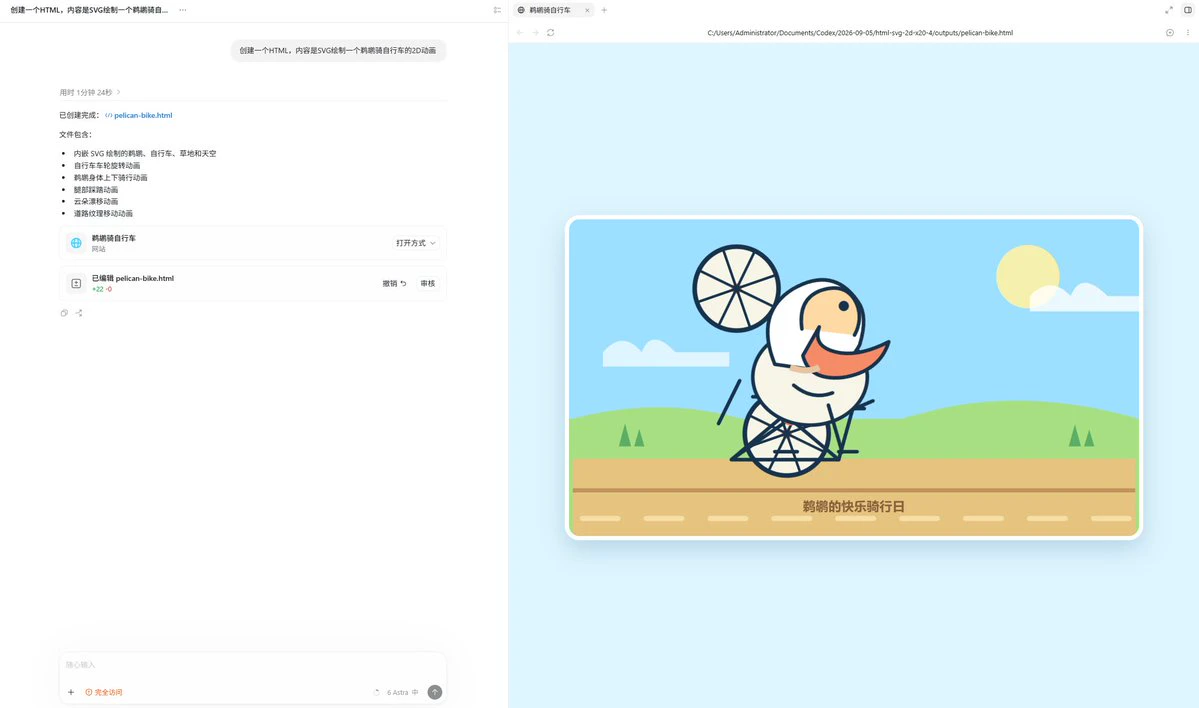
I heard GPT 6 Astra’s frontend is really powerful!
I tried it out—why does the style feel kind of off?
post-image
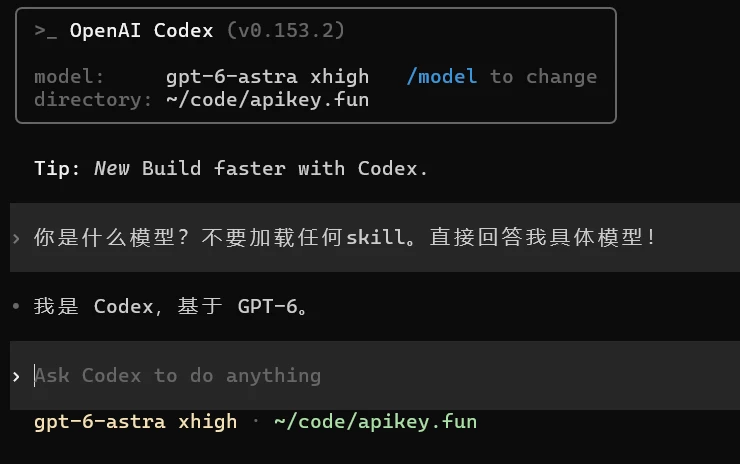
🚨 GPT-6-Astra has quietly become available on the Pro plan!
First, update Codex CLI and the app to the latest version. Although the model switcher is not yet visible on the web, Codex can already be used ahead of the official rollout.
If it is not displayed in the interface, directly modify:
~/.codex/config.toml
model = "gpt-6-astra"
review_model = "gpt-6-astra"
Save the changes and restart Codex to try it.
The web version has not caught up yet, but CLI users can already start using it.
#Codex #GPT6Astra #OpenAI
post-image
AI is already very powerful, but sometimes it’s still powerful in a wonderfully absurd way.
I went to get a haircut and reminded Tony: “Don’t touch my eyebrows.”
Tony: “I wasn’t going to.”
Me: “Good.”
Tony: “But since you mentioned it, I’ll add an acceptance check after the haircut to confirm both eyebrows are still there.”
That’s GPT-5.6-sol:
You remind it not to do something it wasn’t doing in the first place, and it immediately adds a unit test to prove it didn’t.
Doubao — your personal finance expert!
You deserve it!
Doubao — your personal finance expert!
It’s not that bad, is it? Don’t blindly idolize foreign things, okay? 😅
DeepSeek once ignored her, but now she’s a little out of your league!
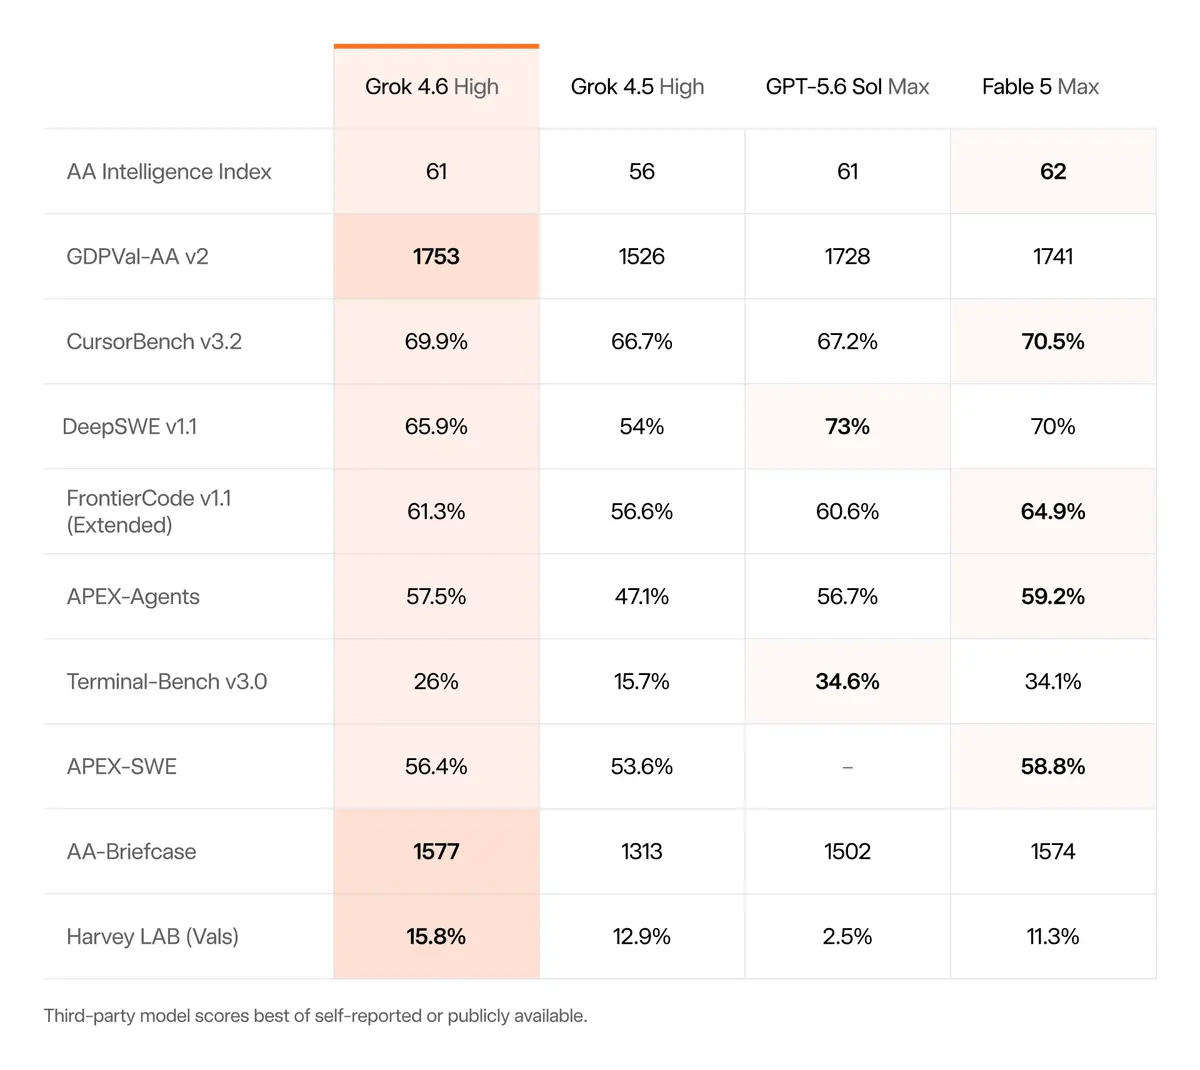
Grok 4.6 is here too!
It was released almost at the same time as DeepSeek-V4-Pro-0813!
Honestly, seeing Grok 4.6's specs still got me pretty excited! Grok 4.5 was already one of my favorite models for everyday use, because it's really fast and has far fewer restrictions, making it ideal for daily use.
This time, however, Grok 4.6 has been brought directly to specs very close to those of the two leading flagship models, while offering faster speed than them.
Musk's Grok has truly made it to the big leagues this time! I think it really can take their place and become a new member of the Big Thre
post-image
Officially announced! DeepSeek-V4-Pro-0813 is coming soon!
Just now, the DeepSeek website documentation officially revealed the model ID for the stable version of DeepSeek-V4-Pro. Based on the date above, it is scheduled for August 13.
The stable version of V4-Pro has also started supporting the Responses API, allowing it to be used directly on Codex without any conversion.
This is insane—OpenAI really went hard this time.
I had just gotten my Pro x20 quota reset, and I was stunned when I checked it.
The weekly quota seems to be only one-third of what it was before.
This isn’t a minor cut—they’ve slashed it to the bone.
Over the past two days, OpenAI’s models have been consistently overloaded, with frequent freezes, throttling, and queues.
So there are only two possibilities:
Either there’s a bug in the quota configuration,
or OpenAI really can’t handle the load anymore and has started proactively tightening Pro users’ quotas.
If it’s the latter, the value of the
The new Codex App uses a third-party API and can’t generate images—here’s the fix.
Recently, many people should have run into this problem:
After integrating the relay station API in the new Codex App, when calling the built-in imagegen skill, the model seems to have already finished generating the image, but the image simply won’t display in the client.
At first I thought the third-party API didn’t return the image correctly. Later, after analyzing Codex’s configuration and request logic, I found that the issue lies in the new client’s permission validation for third-party providers.
It seems
I did a full-day deep体验 of GPT-5.6-sol.
My attitude roughly went through three stages:
Excitement → Doubt → Understanding and acceptance.
First, let’s talk about something that’s easy to get confused:
The highest reasoning level of GPT-5.6-sol itself is still xhigh. What the UI shows as Max and Ultra mostly refers to the client’s workflow modes—not simply making the model “smarter” by tweaking it alone.
The most complained-about thing about Ultra today is that it really likes automatically dispatching a large number of sub-agents.
Even for a task that isn’t that complex, it may ins
Those who haven’t used gpt-5.6-sol yet should really go try it.
I just used the ultra mode to do a full review of my relay project.
It took 1 hour and 32 minutes and ruthlessly uncovered 19 issues.
Honestly, I was stunned.
I’ve always had a habit: do a review before every release. I thought the project was already fairly clean, but it still dug up a bunch of legacy problems.
Now I finally get it:
The shit mountain left by gpt-5.5 has to be cleaned up by gpt-5.6.
As for the shit mountain left by gpt-5.6…
Well, that will have to wait for GPT-6.0.
gpt-5.6-sol has already appeared in the models.json file of the Codex repository.
The context size I care about most is also basically confirmed: 372K. Compared to the previous generation gpt-5.5's 272K, that's an improvement of about 36.7%.
But to be honest, seeing this number still feels a bit disappointing. After all, opus 4.8 and fable-5 have both achieved 1M context, so 372K doesn't seem particularly impressive by current standards.
The good news is that Codex's compression capability has always been strong. After multiple rounds of compression in long tasks, stability remains decent. So