Basel234

vip
Active for: 1.9y
Peak Tier 0
No content yet
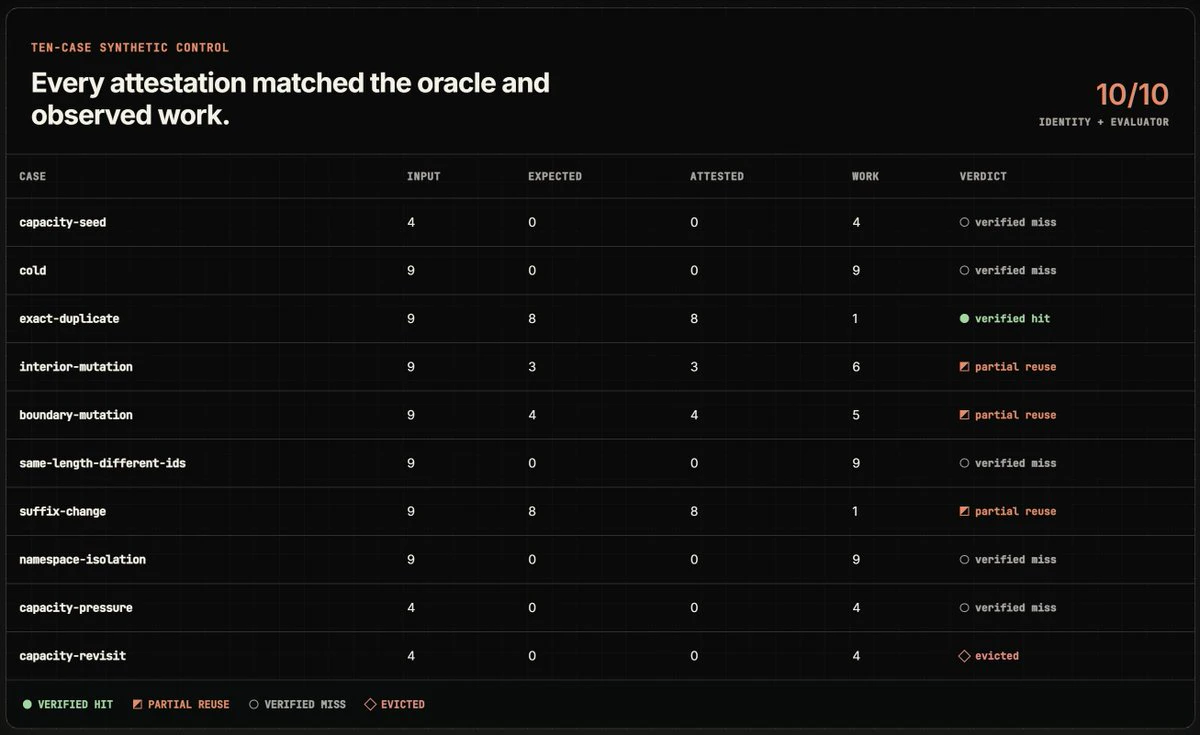
I read an interesting study on token reuse and caching of content
Siddhant Khare (AI Researcher) turned some of these findings into an audit trail where an independent oracle predicts reusable tokens from token identity and cache policy, the engine attests, the prompt path has to show the same work, and cached and no-cache runs must emit identical token arrays.
Basically, zero reuse from cold state and zero reuse from eviction get separate verdicts, and timing stays null rather than zero, since token-level control cannot prove latency savings.
The study confirmed that reuse follows the first c
post-image
What I will cover:
- whale wallets read alongside insider filings and congressional trades
- prediction markets mispriced against that same public information
- routing the resulting trade across 150+ venues
Treated as a research input, not a set of recommendations. I built this because the information was already public and the tooling was the only thing missing.
Free hands-on workshop, open Q&A, plus Premium for registrants.
Laguna S is an 118B mixture-of-experts model that activates only 8B parameters per token
This is definitely worth studying because Poolside took it from training start to launch in just eight weeks! Let that sink in
post-image
What matters for anyone shipping AI products like my team is the factory behind it, fewer than 70 researchers running 10,000 - 20,000 experiments / month, with an immutable data layer that lets them reproduce any past run.
post-image
  • 1
  • 1
Eiso Kant walks through the setup here and reproducibility is what I keep flagging with my teams.
When you ship apps daily, the real win is rerunning last week's experiment and trusting it for new features and scaling it, this sounds much easier than it is :)
The model fits on a single DGX Spark and runs at 30 - 40 tokens per second, beating open-weight systems near 10x its size.
We over-provision because we assume scale is the only lever, but they pulled persistence and backtracking out of a small model instead.
If a team under 70 people can build infra this tight, what does that say about how lean the rest of us builders and operators could run if reproducibility were the first feature instead of the last?
I will be hosting a working session with @FirmAdaptAI on How to Automate Your Small Business Without Overspending on Tuesday, July 14, at 12:00 PM EST
I will walk through how to automate complex business processes, when to use AI agents, & deploy AI in an online store, specifically targeting Shopify, WooCommerce, BigCommerce, Wix, Magento, and Etsy owners
Would love to have you join; you can register for FREE here:
SHOP+0.02%
WIX-1.41%
ETSY-1.34%
I just ran a controlled experiment to quickly gauge the efficacy of off the shelf AI, and here is the result 💀
I was seeing this test and I’m surprised that on June 1, 2026, this is where we are at, we are still very, very early
post-image
Marvell Technology $MRVL is sitting at a composite outperformance score of 83 on the Asset Outperformer Engine (AOE) today with a 30-day return of +36% and Phase B confirmation across all 5 benchmarks.
Seagate $0AD3 is at 73 with +60%, Texas Instruments $TXN at 73 with +35%, and the semis ETF at 75 with +34%.
Semi-exposure is dominating the top of the board across single names and the sector ETF, ranked by relative strength against $BTC, $ETH, $SOL, $Gold, and $SPY rather than a single index.
Same scoreboard: all asset classes side by side.
This benchmark is strong, so assets that outperform i
Please join me in my 2-hour AI Automation & Business Process Reengineering workshop on May 6, at 7:00 PM EST.
It's FREE! You can register here:
It should be really fun, I will go through:
> Live company audits to diagnose operational inefficiencies, costing $
> Interaction with Son of Basel and virtual employees LIVE in real-time
> 90-Day AI Transformation Roadmap for your business
> Open Q&A to talk through industry-specific cases
The real kicker isn't just the size - it's the accuracy.
Verified phone numbers (mobile + work) AND personal/work emails that actually connect. Not those dead leads that waste your SDRs' time and kill your sender reputation.
Real-time updates wherever possible
Here's what most people don't realize about contact data:
Static databases die fast. A contact list that was 90% accurate 6 months ago? Probably 60% accurate today.
People change jobs, emails, and phone numbers. Your outreach dies with stale data.
The shift is real: teams are moving from 'spray and pray' email to multichannel outreach.
You need verified mobile numbers for calls/SMS + multiple email touchpoints. One bad database kills your entire sequence.
QUESTION: How often does YOUR contact data refresh?
Welcome to our live show!
Indonesian Rupiah ($IDR) Take Over!
@blockcircle Alpha Hunter has been detecting /IDR denominated tokens listings non-stop the past few hours; namely on the largest CEX @ (it partners already with @Tokocrypto) 👀
post-image